train and test a simple image classifier on photos of my texture swatches, and argue from the results what a machine learns about a surface and what it misses.
Instruction
In Lesson 1.1 you learned how a model generates images. Today you meet the other side of machine learning: a model that classifies, sorting images into categories it has been trained on. You will build one yourself, in a few minutes, and then critique it.
How a classifier learns. You give the model examples in labeled groups — say, twenty photos of “rough” swatches and twenty of “smooth”. The model adjusts millions of internal numbers until it can predict the right label for your examples. Then you show it an image it has never seen and it outputs its best guess, with a confidence score. Teachable Machine, which we use today, speeds this up with transfer learning: it starts from a model already trained on a large general image collection and retrains only the last step on your examples.
Privacy. Teachable Machine trains the model inside your web browser and needs no account to train or test. According to its own documentation, your images are not stored on Google’s servers unless you choose to save the project to Google Drive — so do not save. If you have no device or connection, the lesson’s reading holds a complete illustrative run you can analyze on paper. Use only photos of swatches, never of people.
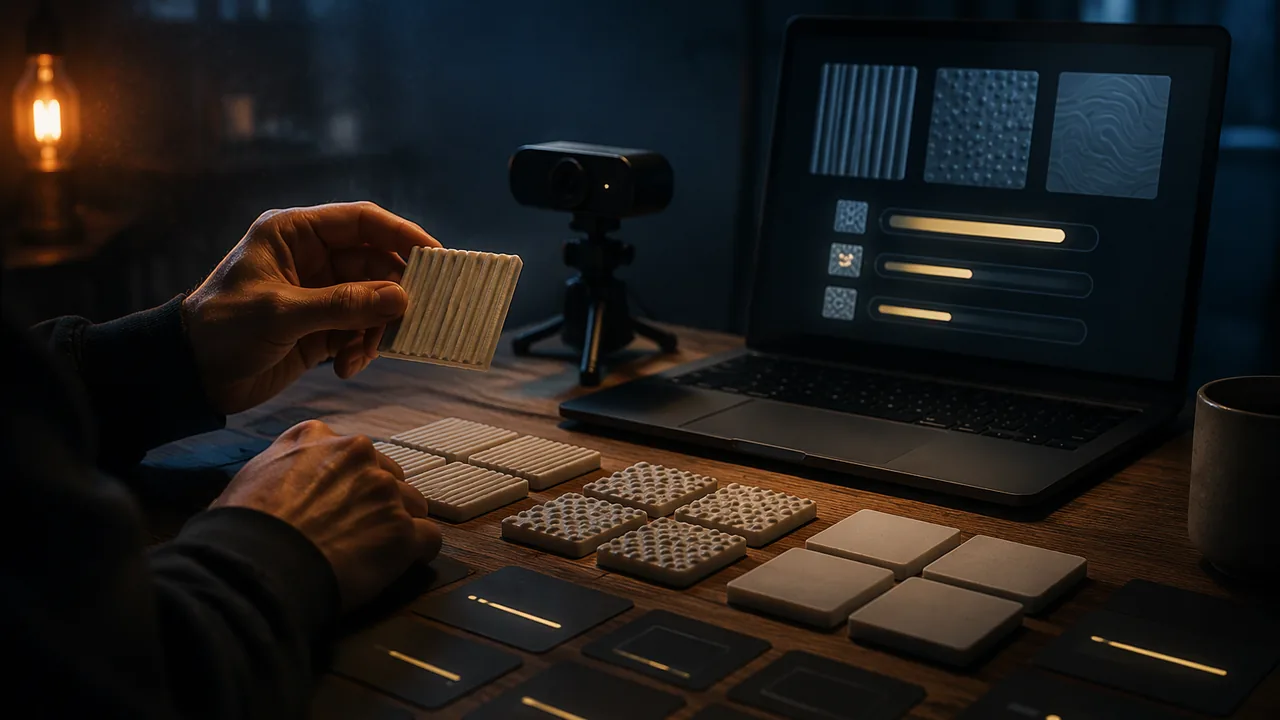
The experiment. Make three classes from your texture library, such as ridged, bumpy and smooth. Photograph each swatch several times from slightly different angles. Train. Then test with swatches the model has not seen — including ones photographed under different light.
What you will probably find. The model often does well on photos like its training photos and badly when the light changes. That is because it learned patterns of pixels — edges, shadows, contrasts — not surfaces. A ridged swatch under flat light may be read as “smooth” because its ridges cast no shadows. A human hand would never make that mistake. Some testers also find the model latched on to something irrelevant, such as the color of the swatch or the table behind it. That is a small, visible version of a serious problem: a model learns whatever patterns separate its training examples, including accidental ones.
From swatches to society. If a model trained on photos under one kind of light fails under another, what happens to a model trained mostly on photos of some kinds of people, places or art? Bias in AI often begins exactly like this — with who and what was in the training set.
Discussion question. Can a machine that has never touched anything learn texture? Take a position and defend it with evidence from your test record. “Partly, because…” is a legitimate position if you say exactly which part.
📖 Read for this lesson
The reading opens over the lesson; close it to come back to exactly where you were. The checks below draw on it.
Formative check
Work through these before moving on. They are not graded — they tell you whether the standard below has landed yet.
Simulation & tools
Train a texture classifier
Open Teachable Machine’s image project (no sign-in; do not save to Drive). Rename the classes ridged, bumpy and smooth. Upload 10-15 raking-light photos of your swatches to each class (or use the webcam pointed only at swatches). Click Train Model. Then test with three swatches the model has not seen, first in raking light and then in flat overhead light. Record the predicted class and confidence for all six tests. Answer: did changing the light change the prediction, and what does that show about what the model learned? No device or connection? Use the complete illustrative run in this lesson’s reading: record its six tests as your test record and answer the same question from them.
Open Teachable Machine ↗ · Teachable Machine, Google · free to use; Google terms (models train in the browser)
You train a classifier only on photos of ridged swatches taken in strong side light. You test it on a ridged swatch photographed under flat overhead light. What happens?
Your classifier labels every blue swatch “smooth”. The most likely reason is:
Position statement: Can a machine that has never touched anything learn texture? Answer in 150-200 words with at least two results from your test record as evidence, and connect your answer to one way bias can enter an AI system.
How confident are you that you can explain what an image classifier learns from examples and why it can fail?
A Classifier Experiment on Record: Confusion Tables, n and Published Benchmarks
SLS original illustrative experiment record; published figures from arXiv:1311.3618 and arXiv:1811.12231, retrieved 26 Sept 2026 · SLS original (constructed, illustrative data); short facts and figures from arXiv papers (arXiv non-exclusive license)
Why this reading. The lab asks you to train a classifier, record six tests, and argue from your results what a machine learns about texture. You may not have a device, a connection or good swatch photos. So this reading holds a complete record of a run, with counts, that you can analyze without a computer, and the published findings to set beside it. The experiment record below is illustrative: SLS original, invented for this course, not from any real student, company or tool. The published numbers are real and cited.
The setup of the illustrative run
Three classes: ridged, bumpy, smooth. Training set: 12 photographs per class, 36 in all, every one taken in raking light (one lamp low on one side, so ridges cast shadows). Test set: 10 swatches per class that the model had never seen, 30 in all, photographed twice: once in raking light (Test A) and once in flat overhead light (Test B). Rows are the true class; columns are what the model predicted.
| Test A: raking light, n = 30 | |||
|---|---|---|---|
| True predicted | ridged | bumpy | smooth |
| ridged | 9 | 1 | 0 |
| bumpy | 1 | 8 | 1 |
| smooth | 0 | 1 | 9 |
| Test B: flat overhead light, same 30 swatches, n = 30 | |||
|---|---|---|---|
| True predicted | ridged | bumpy | smooth |
| ridged | 3 | 2 | 5 |
| bumpy | 2 | 5 | 3 |
| smooth | 0 | 1 | 9 |
Totals (SLS calculation). Test A: 9 + 8 + 9 = 26 correct of 30, or 86.7%. Test B: 3 + 5 + 9 = 17 correct of 30, or 56.7%. Guessing at random among three classes would score about 33.3%. Each photograph is worth 3.3 percentage points, so a change of one or two photographs is not evidence of anything; a change of nine is. Per class in Test B: ridged 30% right, bumpy 50%, smooth 90%. And of the 17 photographs the model called smooth in Test B, only 9 were smooth (53%).
The six-test record, in the form the lab asks for
| Swatch (not in training) | Light | Predicted | Confidence |
|---|---|---|---|
| Corrugated card, ribs | raking | ridged | 94% |
| Corrugated card, ribs | flat | smooth | 81% |
| Bubble wrap | raking | bumpy | 88% |
| Bubble wrap | flat | bumpy | 52% |
| Felt | raking | smooth | 90% |
| Felt | flat | smooth | 93% |
A second illustrative run trained on smooth swatches of which 10 of 12 were blue. Tested on a blue corduroy swatch (ridged), the model said smooth, 97% confidence; on a gray smooth swatch it said bumpy, 64%.
What published research adds
- Describable Textures Dataset (Cimpoi, Maji, Kokkinos, Mohamed, Vedaldi, arXiv:1311.3618, 2013): 5,640 photographs sorted into 47 human-chosen texture words, 120 images each, collected from Google and Flickr. Its purpose was to teach machines the words people use for texture.
- Geirhos and co-authors (arXiv:1811.12231, 2018; ICLR 2019) pitted texture against shape by giving image classifiers a picture whose shape said one object and whose texture said another. Human observers followed shape in 95.9% of their correct decisions; the ResNet-50 network followed texture 77.9% of the time. So a network trained on photographs does lean hard on texture statistics, yet, as the illustrative run shows, a small classifier can read a photograph’s shadows rather than a surface.
Building a position statement (150–200 words)
- Claim: “A machine that has never touched anything can learn (all / part / none) of what texture is.” If “part,” name the part.
- Evidence: at least two numbers from the record, for example Test A against Test B.
- Explanation: shadows are a cue for depth, and the model learned the cue, not the depth.
- Bias link: the blue-smooth run shows a model learning an accident of its training set; ask who and what was in the training set of any system that judges people or art.